OpenAI plans to buy Google's TPU chips.
Reported by The Information, relayed by Reuters. Reuters: OpenAI plans to buy Google's AI chips, The Information reports (opens in a new tab)
Esta sección aún no está traducida. El contenido siguiente se muestra en inglés, tal como se publicó. Leer la versión en inglés.
Last reviewed · How we check sources
AI models · updated 1 Nov 2026
109 current models from 17 labs, across text, image, video, voice and embeddings. Tell the finder your task, priorities and must-haves and it shortlists the five best fits, with the reason for each and the trade-offs. Prices come from each lab's own pricing page. Quality and speed come from one independent source, Artificial Analysis, so models are measured the same way. Nothing is estimated: a dash means not published. For tools built on these models, see the AI agent finder.
109
models compared
17
labs
27
with open weights
85
with a published token price
57 of 109 models match. Filtered out: 6 for limited access (tick Include preview and limited), 15 for your constraints. Weights: quality 4, price 1, speed 1, context 1.
Google · Text
Why: Strong on quality and context: Artificial Analysis index 50, 1.05M token context.
Which level: medium (the default). Google documents the levels low, medium, high but publishes no per-level advice. ai.google.dev (opens in a new tab)
US$2 in / US$10 out per 1M ai.google.dev (opens in a new tab) · about US$200.00 a month at your volume
Anthropic · Text
Why: Strong on quality and context: Artificial Analysis index 48, 1M token context.
Which level: medium (the default). Anthropic: Balanced. Agentic tasks that need a balance of speed, cost and performance. platform.claude.com (opens in a new tab)
US$4 in / US$20 out per 1M docs.anthropic.com (opens in a new tab) · about US$400.00 a month at your volume
OpenAI · Text
Why: Strong on quality and context: Artificial Analysis index 51, 1.05M token context.
Which level: medium. OpenAI: When quality and reliability matter. The default for most workloads and a balanced point for latency, performance and cost. developers.openai.com (opens in a new tab)
US$10 in / US$50 out per 1M developers.openai.com (opens in a new tab) · about US$1000.00 a month at your volume
OpenAI · Text
Why: Strong on quality and context: Artificial Analysis index 46, 1.05M token context.
Which level: medium (the default). OpenAI: When quality and reliability matter. The default for most workloads and a balanced point for latency, performance and cost. developers.openai.com (opens in a new tab)
US$2 in / US$10 out per 1M developers.openai.com (opens in a new tab) · about US$200.00 a month at your volume
1. Filters first: the task sets the model type and required features, then your constraints, context and budget. 2. For the models left, each measure is scaled from 0 to 100 against the others in the running: quality is the Artificial Analysis Intelligence Index, price is the blended price per 1M tokens at your input and output mix (lower is better, log scale), speed is output tokens a second from Artificial Analysis (log scale), context is the context window (log scale). 3. Fit is the weighted average, using the weights shown. A missing figure scores zero and is flagged, so a gap never helps. "EU-based lab or open weights" means the lab is headquartered in the EU, or you can run the weights yourself. Figures checked 1 Nov 2026. This is arithmetic on published figures, not a recommendation.
Pick two to four models, here or with the Compare box on any result card or table row.
A dash means the figure is not published on the sources we checked, so we leave it blank rather than estimate. Click a model name for its full sourced profile.
Generally available text models with published figures. Dashed lines mark the median, so the top left of each chart is above-median results for below-median price. Hover or tap a dot for its source.
Quality: Artificial Analysis Intelligence Index v5.0 at each model's best tested setting.
| Model | Index | Blended US$/1M |
|---|---|---|
| GPT-6 Astra | 57 | 20.000 |
| GPT-6.1 Sol | 55 | 4.000 |
| GPT-6.1 Terra | 51 | 2.000 |
| GPT-6 Luna | 28 | 0.200 |
| Claude Fable 5.1 | 50 | 20.000 |
| Claude Opus 5.5 | 58 | 8.000 |
| Claude Sonnet 5.5 | 54 | 4.000 |
| Claude Haiku 5.5 | 36 | 0.200 |
| Gemini 4 Argon | 50 | 4.000 |
| Gemini 3.8 Flash | 31 | 1.500 |
| Gemini 3.5 Flash-Lite | 12 | 0.850 |
| Grok 4.7 | 35 | 3.000 |
| Muse Wonder | 43 | 8.000 |
| Mistral Large 4 | 26 | 1.050 |
| Mistral Small 4 | 4 | 0.262 |
| DeepSeek V4.1 Flash 1017 | 32 | 0.525 |
| DeepSeek V4 Pro | 23 | 1.980 |
| Qwen3.8-Max | 34 | 3.000 |
| Kimi K3.1 Pro | 46 | 4.000 |
| GLM-5.3 | 32 | 2.150 |
| GLM-5.3-Flash | 28 | 0.237 |
| MiniMax M3.1 Flash | 29 | 0.262 |
| MiniMax M3 | 19 | 0.525 |
| MiMo-V2.6-Pro | 30 | 0.544 |
| MiMo-V2.6-Flash | 27 | 0.175 |
| Step 5 Preview | 29 | 1.425 |
Speed: output tokens a second measured by Artificial Analysis at the same setting as the index.
| Model | Tokens/s | Blended US$/1M |
|---|---|---|
| GPT-6 Astra | 78 | 20.000 |
| GPT-6.1 Sol | 79 | 4.000 |
| GPT-6.1 Terra | 97 | 2.000 |
| GPT-6 Luna | 118 | 0.200 |
| Claude Fable 5.1 | 62 | 20.000 |
| Claude Opus 5.5 | 97 | 8.000 |
| Claude Sonnet 5.5 | 139 | 4.000 |
| Claude Haiku 5.5 | 235 | 0.200 |
| Gemini 4 Argon | 83 | 4.000 |
| Gemini 3.8 Flash | 120 | 1.500 |
| Gemini 3.5 Flash-Lite | 406 | 0.850 |
| Grok 4.7 | 78 | 3.000 |
| Muse Wonder | 143 | 8.000 |
| Mistral Large 4 | 161 | 1.050 |
| Mistral Small 4 | 172 | 0.262 |
| Ministral 3 8B | 91 | 0.150 |
| DeepSeek V4.1 Flash 1017 | 175 | 0.525 |
| DeepSeek V4 Pro | 81 | 1.980 |
| Qwen3.8-Max | 40 | 3.000 |
| Kimi K3.1 Pro | 31 | 4.000 |
| GLM-5.3 | 76 | 2.150 |
| GLM-5.3-Flash | 69 | 0.237 |
| MiniMax M3.1 Flash | 119 | 0.262 |
| MiniMax M3 | 106 | 0.525 |
| MiMo-V2.6-Pro | 49 | 0.544 |
| MiMo-V2.6-Flash | 45 | 0.175 |
| Step 5 Preview | 165 | 1.425 |
Most 2026 models offer about 1M tokens, so context rarely separates them. Price decides.
| Model | Input US$/1M | Context |
|---|---|---|
| GPT-6 Astra | 10 | 1.05M |
| GPT-6.1 Sol | 2 | 1.05M |
| GPT-6 Sol | 2 | 1.05M |
| GPT-6.1 Terra | 1 | 1.05M |
| GPT-6 Luna | 0.1 | 1.05M |
| GPT-5.6 Sol | 4 | 1.05M |
| GPT-5.6 Terra | 2 | 1.05M |
| GPT-5.6 Luna | 0.2 | 1.05M |
| GPT-5.5 | 5 | 1.05M |
| GPT-5.5 Pro | 30 | 1.05M |
| GPT-5.4 | 2.5 | 1.05M |
| GPT-5.4 Pro | 30 | 1.05M |
| GPT-5.4 mini | 0.75 | 400K |
| GPT-5.4 nano | 0.2 | 400K |
| GPT-5.3-Codex | 1.75 | 400K |
| Claude Fable 5.1 | 10 | 1M |
| Claude Opus 5.5 | 4 | 1M |
| Claude Sonnet 5.5 | 2 | 1M |
| Claude Haiku 5.5 | 0.1 | 1M |
| Gemini 4 Argon | 2 | 1.05M |
| Gemini 3.8 Flash | 0.75 | 1.05M |
| Gemini 3.5 Flash-Lite | 0.3 | 1.05M |
| Grok 4.7 | 2 | 500K |
| Grok 4.6 | 2 | 500K |
| Grok 4.5 | 2 | 500K |
| Grok 4.3 | 1.25 | 1M |
| Grok 4.20 | 1.25 | 1M |
| Grok 4.20 Multi-Agent (beta) | 1.25 | 1M |
| Grok Build 0.1 | 1 | 256K |
| Muse Wonder | 4 | 1.05M |
| Muse Spark 1.3 | 1.25 | 1.05M |
| Mistral Large 4 | 0.7 | 1.05M |
| Mistral Small 4 | 0.15 | 262K |
| Ministral 3 8B | 0.15 | 262K |
| DeepSeek V4.1 Flash 1017 | 0.3 | 1M |
| DeepSeek V4 Pro | 1.32 | 1M |
| Qwen3.8-Max | 2 | 1M |
| Qwen3.8-Flash | 0.15 | 1M |
| Kimi K3.1 Pro | 2 | 1.05M |
| Kimi K3.1 Pro Highspeed | 4 | 1.05M |
| Kimi K3 | 3 | 1.05M |
| GLM-5.3 | 1.4 | 1M |
| GLM-5.3-Flash | 0.15 | 1M |
| MiniMax M3.1 Flash | 0.15 | 1M |
| MiniMax M3 | 0.3 | 1M |
| MiMo-V2.6-Pro | 0.435 | 1.05M |
| Step 5 Preview | 1 | 1M |
26 generally available text models with an official token price and an independent quality score, cheapest first. Prices are each lab's standard list price in US dollars, checked 1 Nov 2026. Blended price weights three input tokens to one output token.
Quality index: Artificial Analysis Intelligence Index at each model's best tested setting. Long-context, batch and cached rates differ, see each model page.
ChatGPT, Claude and Gemini are apps. Each runs on a family of models from its lab, OpenAI, Anthropic and Google. Below are the highest-scoring and the cheapest scored model from each, with official API prices.
| App | Top scored model | Index | Price in / out per 1M | Cheapest scored model | Price in / out per 1M |
|---|---|---|---|---|---|
| ChatGPT (OpenAI) | GPT-6 Astra | 57 | US$10 / US$50 developers.openai.com (opens in a new tab) | GPT-6 Luna | US$0.1 / US$0.5 developers.openai.com (opens in a new tab) |
| Claude (Anthropic) | Claude Opus 5.5 | 58 | US$4 / US$20 docs.anthropic.com (opens in a new tab) | Claude Haiku 5.5 | US$0.1 / US$0.5 docs.anthropic.com (opens in a new tab) |
| Gemini (Google) | Gemini 4 Argon | 50 | US$2 / US$10 ai.google.dev (opens in a new tab) | Gemini 3.5 Flash-Lite | US$0.3 / US$2.5 ai.google.dev (opens in a new tab) |
Index: Artificial Analysis Intelligence Index. App plan prices and limits are on each maker's pricing page. Chat assistants and their agents are compared in the agent finder.
The 10 highest-scoring text models on the Artificial Analysis Intelligence Index, with their list price. This is one independent measure of general capability, not a verdict for every job. For coding, compare the coding agents that use these models.
75 models from 17 labs, 27 with open weights
9 models from 4 labs, 0 with open weights
2 models from 2 labs, 0 with open weights
17 models from 7 labs, 0 with open weights
3 models from 2 labs, 0 with open weights
Facts computed from the table, not a ranking. Limited-access models are left out. Prices for image, video and voice models are per token of that medium, so compare them only within a category.
Pieces of text a model reads and writes. Prices are per 1 million tokens.
For data centres: Every token is GPU work in a data centre, so token volume tracks compute and power use.
How many tokens the model can hold in one request.
For data centres: Long contexts need more accelerator memory and compute for each request.
Reading your prompt and writing the answer are billed separately. Output usually costs more.
For data centres: Output tokens are produced one at a time, so long answers keep accelerators busy for longer.
Open weights can be downloaded and run on your own servers.
For data centres: Self-hosting moves the power and cooling load into your own or a colocation facility.
Test scores, usually published by the model maker. Settings vary.
For data centres: Treat as claims. A higher score with many more tokens per task can mean more energy per task.
Plain-language explanations by CoolPower Index, not figures. For measured electricity use see the agents page and the IEA's Energy and AI report.
Enter a monthly token volume to see the list-price cost on each model with a published token price.
For scale: 1M tokens is roughly 750,000 English words, using MiniMax's published rule of thumb of about 750 words per 1,000 tokens. platform.minimax.io (opens in a new tab)
List prices for standard requests, before caching, batch or volume discounts. Notes such as peak-hour rates and price changes are in the table above. Models with no published token price are not included.
Solid ring: open weights released for the model on this page. Dashed: closed, not yet released or not stated. All circles are the same size on purpose, this is not a ranking.
| Model | Test | Score | Published by | Date |
|---|---|---|---|---|
| GPT-6.1 Terra | Terminal-Bench 4.0Maximum reasoning effort | 50.3% | OpenAI (opens in a new tab) | 2026-10-26 |
| Claude Sonnet 5.5 | Terminal-Bench 4.0 | 70.6% | Anthropic (opens in a new tab) | 2026-10-07 |
| Claude Haiku 5.5 | Terminal-Bench 4.0 | 39.2% | Anthropic (opens in a new tab) | 2026-10-07 |
| Claude Haiku 5.5 | OSWorld 2.1 (offline subset) | 72.4% | Anthropic (opens in a new tab) | 2026-10-07 |
| Gemini 4 Carbon | SEC-bench Pro | 88.2% | Google (opens in a new tab) | 2026-10-28 |
| Gemini 4 Carbon | CWE-bench | 71% | Google (opens in a new tab) | 2026-10-28 |
| Grok 4.7 | CursorBench 4.0 | 46.3% | xAI (opens in a new tab) | 2026-09-21 |
| Mistral Large 4 | Terminal-Bench 4.0 | 41% | Mistral, citing Artificial Analysis (opens in a new tab) | 2026-10 |
| DeepSeek V4.1 Flash 1017 | DeepSWE v1.1 | 77% | DeepSeek (opens in a new tab) | 2026-10-17 |
| Qwen3.8-Max | Terminal Bench 2.1 | 86.6% | Alibaba (opens in a new tab) | 2026-08-03 |
| Kimi K3.1 Pro | Terminal-Bench 4.0Claude Code harness, max effort | 65.7% | Moonshot (opens in a new tab) | 2026-10-23 |
| GLM-5.3 | Terminal Bench 3.0 | 28.3% | Z.ai (opens in a new tab) | 2026-08-14 |
Different tests and settings, so rows are not comparable with each other.
from agents import Agent, Runner

agent = Agent(name="Assistant", instructions="You are a helpful assistant")

result = Runner.run_sync(agent, "Write a haiku about recursion in programming.")
print(result.final_output)from google import genai
client = genai.Client()
interaction = client.interactions.create(
model="gemini-4-argon",
input="Write a three.js script that renders a realistic 3D black hole with gravitational lensing."
)
print(interaction.output_text)from google.adk import Agent
from google.adk.tools import google_search
agent = Agent(
name="researcher",
model="gemini-flash-latest",
instruction="You help users research topics thoroughly.",
tools=[google_search],
){
"model": "glm-5.3",
"thinking": { "type": "enabled" },
"reasoning_effort": "max"
}Reported by The Information, relayed by Reuters. Reuters: OpenAI plans to buy Google's AI chips, The Information reports (opens in a new tab)
Reported by The Information. Bloomberg. The Next Web: Nvidia in talks to guarantee debt for Nscale's Anthropic data centre (opens in a new tab)
Reported by Bloomberg first. CNBC and Reuters from a source. CNBC: Anthropic in talks for second $45 billion Nscale data center deal: source (opens in a new tab)
Reported by Elon Musk on the SpaceX results livestream, reported by TechCrunch. TechCrunch: SpaceX's AI business is beating expectations (opens in a new tab)
Official uploads. Nothing loads from YouTube until you press play.
109 models are here. For the products and frameworks that put them to work, use the agent finder. Latest launches are in AI news.
Vendor-neutral. A shortlist is arithmetic on published figures with your weights, not a recommendation. Prices change often: check the linked page before you buy. Figures checked 1 Nov 2026.
Google 
DeepMind says its new vision-language-action model, built with Gemini 4 Argon, was tested on more than 200 tasks, finishes tasks 20% to 30% faster than the previous version and packed automotive parts with a 96% success rate in proof-of-concept tests at Mercedes-Benz. It is rolling out through partners including Agile Robots, Apptronik and Boston Dynamics. The figures are DeepMind's own; more robot training and inference means more GPU demand in data centres.
OpenAI
CNBC confirmed OpenAI is now seeking up to US$20bn, down from about US$30bn, and the FT put the post-money valuation at US$1.25tn. The round is still open. Less fresh equity means more scrutiny of every gigawatt OpenAI has signed for.
Source: CNBC (opens in a new tab)
Google
Google says it will support a shared AI training control in robots.txt, alongside Microsoft, OpenAI and Anthropic. It is based on an IETF draft. Website owners get one switch instead of one per crawler.
Amazon
Amazon repeated its outlook: "We continue to expect 2026 cash capital expenditures to be approximately $220 billion."
6 leaders and researchers who shape the models, chips and data centres. Roles are as stated on each linked page. Photos are freely licensed and credited on each card.
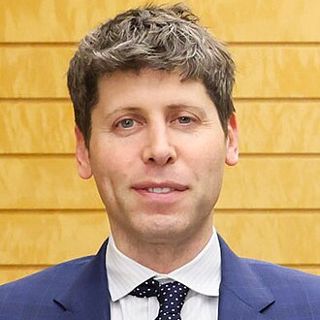
Labs
OpenAI
CEO of OpenAI since 2019.
Source: Wikipedia: Sam Altman (opens in a new tab), accessed 1 November 2026
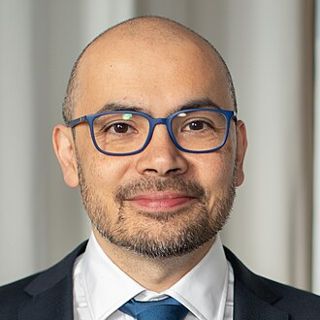
Labs 
Google DeepMind
Co-founder of Google DeepMind and CEO of Isomorphic Labs. Shared the 2024 Nobel Prize in Chemistry for protein structure prediction.
Source: Wikipedia: Demis Hassabis (opens in a new tab), accessed 1 November 2026
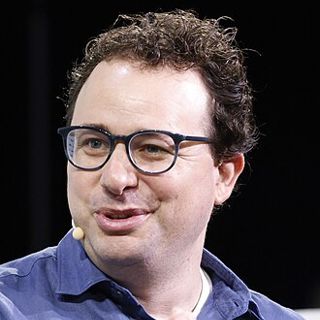
Labs
Anthropic
Co-founder and CEO of Anthropic, founded in 2021 with Daniela Amodei.
Source: Wikipedia: Dario Amodei (opens in a new tab), accessed 1 November 2026
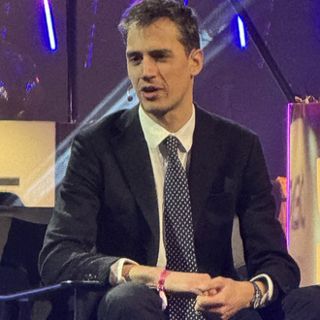
Labs 
Mistral AI
Co-founder and CEO of Mistral AI, Paris.
Source: Wikipedia: Arthur Mensch (opens in a new tab), accessed 1 November 2026
Labs 
DeepSeek
Founder and CEO of DeepSeek and co-founder of the hedge fund High-Flyer.
Source: Wikipedia: Liang Wenfeng (opens in a new tab), accessed 1 November 2026
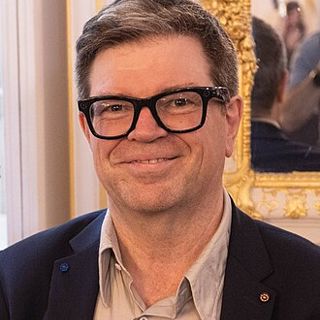
Researchers
NYU and AMI Labs
Professor at NYU. Former Chief AI Scientist at Meta. Co-founded Advanced Machine Intelligence Labs in December 2025.
Source: Wikipedia: Yann LeCun (opens in a new tab), accessed 1 November 2026
Not fact. Everything in this section is a rumour, a theory or a forecast. Each card says where it circulates and sits beside what is actually known, with its own source. We do not endorse any of it, and none of it is investment advice.
Rumour (0)Speculation (0)Prediction (3)
The claim
Joachim Klement, head of market strategy at Panmure Liberum, says his core conviction is that the AI bubble bursts in 2027 or 2028. His year-end 2027 target for the S&P 500 is 5,000 points, which he put at 36% below the level at the time.
Circulates in: Bloomberg, via Yahoo Finance: AI Bubble Risks Worst S&P 500 Crash Since 2008, Strategist Says (opens in a new tab)
What is known
The claim
Capital Economics forecasts the S&P 500 at 6,500 by the end of 2027, about 16% lower, if air keeps leaking out of the AI trade or the bubble bursts. It also expects a final tech-led rally in 2026 first.
Circulates in: CNBC: Firm that correctly called the AI rally slowdown says here's where to hide out (opens in a new tab)
What is known
The claim
Gartner analyst Will Sommer predicts some US$3.5tn of AI infrastructure spending could be written off by the end of 2030, and that 80% of neoclouds will stop operating independently by 2030, bought or gone under.
Circulates in: The Telegraph: The tech 'death spiral' that could destroy the AI boom (opens in a new tab)
What is known
Checked 1 November 2026. Rumour means an unconfirmed report of a specific event. Speculation means a theory or interpretation. Prediction means a forecast with a date or a number. See all rumours, theories and predictions Not investment advice.
The trained "brain" behind an AI app. You give it text, pictures or sound and it gives an answer back. It does not act on its own.
A small chunk of text, often part of a word. AI companies charge by the million tokens, a bit like paying for electricity by the unit.
Why it matters Long documents and chats use more tokens, so they cost more.
Tell the Model Finder what you need it for and your budget, and it suggests models that fit, with prices from each company's own price page.
Prices were checked on the date shown on the page and each one links to the company's own price page, which is always the final word.
The company has published the model so anyone can download it and run it on their own computers.
Why it matters It is like a recipe being published instead of only selling the cake.
Among generally available models on the independent Artificial Analysis Intelligence Index, checked on 1 November 2026, Claude Opus 5.5 scores 58, GPT-6 Astra scores 57 and GPT-6.1 Sol scores 55. Gemini 4 Carbon scores 59 but is open only to selected partners so far.
Why it matters The top scores are within a point or two of each other, so price, speed and your own tests usually decide.
Source: Artificial Analysis leaderboard, checked 1 November 2026
At list prices per million tokens, GPT-6.1 Sol costs US$2 in and US$10 out, Claude Sonnet 5.5 costs US$2 in and US$10 out, and Gemini 4 Argon costs US$2 in and US$10 out. The top models cost more: GPT-6 Astra is US$10 in and US$50 out, and Claude Opus 5.5 is US$4 in and US$20 out.
Why it matters The mid-tier models from the three labs now cost the same per token, so quality and features decide.
Source: OpenAI, Anthropic and Google pricing pages, checked 1 November 2026
Among the text models we list with an independent quality score, Xiaomi's MiMo-V2.6-Flash is cheapest at US$0.14 per million input tokens and US$0.28 per million output tokens. GPT-6 Luna and Claude Haiku 5.5 both cost US$0.10 in and US$0.50 out. The pricing table on this page is sorted from cheapest to dearest.
Why it matters Cheap models are good for simple, high-volume jobs such as sorting or tagging text.
Source: Xiaomi MiMo, OpenAI and Anthropic pricing pages, checked 1 November 2026